Solutions
Company
Resources



Cut data cleaning costs by 70%+ and eliminate the overhead of manually defining remediation specifications or maintaining bespoke cleaning scripts. Axolotl addresses the most complex data quality issues in your datasets with mathematical precision, avoiding non-deterministic code execution, LLM hallucinations, and unpredictable token costs.
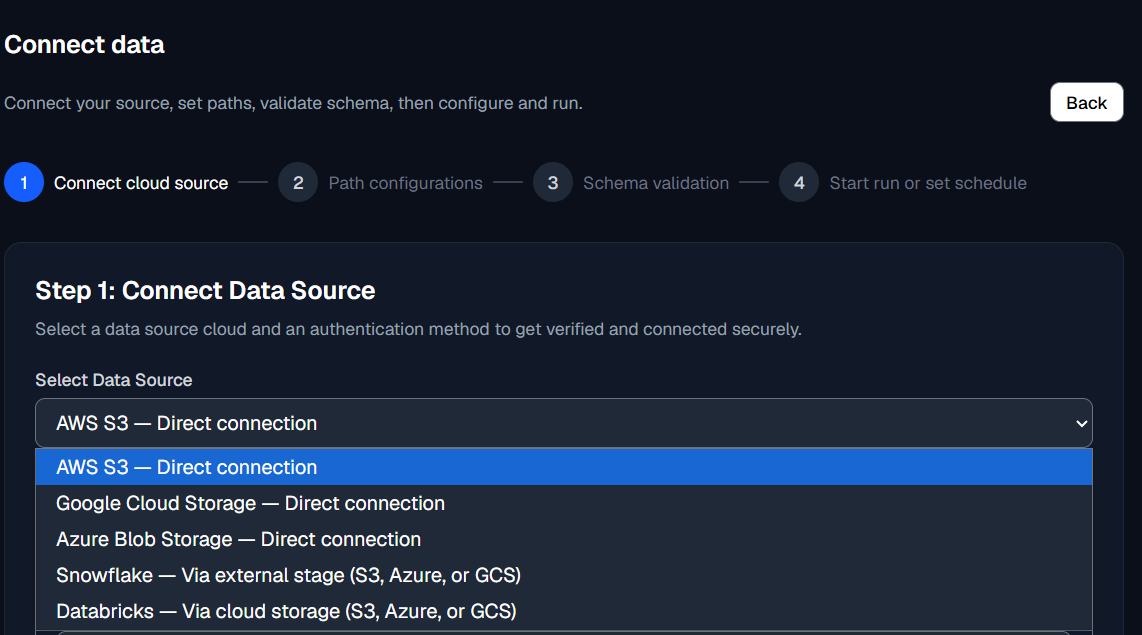
Connects with leading cloud platforms, offers a simple no-code UI requiring minimum configuration - Axolotl can work on its own or integrate to your existing data infrastructure as a data quality layer effortlessly. Set up in minutes and see results from day one.
Automatically validates and standardizes schemas across every file in your dataset, enforcing structural consistency without manual mapping. It detects drift, resolves mismatches, and aligns formats in a single pass—eliminating the silent data quality issues and delivering clean, interoperable data that can be trsuted for the subsequent stages of your pipeline or stack.
Using advanced fuzzy match algorithms, Axolotl detects fuzzy-matched duplicates at scale with high accuracy—no human supervising loops required. It compares match scores across complex string patterns, collapses redundant records cleanly with multi-criteria optimization, and preserves data integrity while dramatically reducing storage and noise.
Automatically identifies outliers especially unusual values and statistics in your datasets with ensemble anomaly detection. The solution proactively flags and fixes issues at scale, mitigates risks in your datasets from the point of action.
Axolotl uses unique research-grade semi-supervised learning for synthetic imputation to fill the gaps or recover missing entries with high-fidelity precision. Unlike standard enrichment that drags in errors from external sources of unknown sovereignty, our specialized models guarantee internal consistency and data integrity.
Customer tabular data is never stored on persistent storage, nor is it ever used to train global models or AI agents. The heavy lifting is handled by our specialized ML models for maximum accuracy, security and interpretability. Your security posture and data lineage remain fully protected and preserved.
Automates the entire workflow in a built-in DQ pipeline including process orchestration, compute resource provisioning, multi-stage feature engineering, training specialized models, tracking progresses, granular audits, human-in-the-loop (HITL) reviews, writing back fixed data, documenting results. Resolves the most prominent data quality issues: inconsistencies, redundancies, inaccuracies, human errors, incompleteness, all end-to-end automated. No manual rule creation is required.
Our AI data quality product Axolotl is built with research‑grade analytical models in secure VPC environment that strictly adheres to data compliances. The cost of a data quality run is measured in Data‑Qualifying Units (DQUs), where the consumed DQUs for each run represents 1GB of logical data successfully remediated, multiplied by the task complexity factor for that run.
Our engine operates on the logical data volume (the total count of records and attributes), ensuring consistent pricing regardless of your storage format. Whether your data arrives as uncompressed text (CSV) or high-efficiency columnar storage (Parquet), your DQU consumption is calculated based on the logical data remediated.
Most platforms prioritize data ingestion and 'ownership' to create vendor lock-in. We focus on stateless processing, leaving governance & lineage fully under customer control. Our data quality engine utilizes session-based, ephemeral machine learning models that process data in a secure, isolated cloud environment. Our Zero-Footprint Framework:
Statelessness: All customer data is processed in volatile memory (RAM) with ephemeral container storage, cryptographically isolated and automatically destroyed upon completion of each run.
Instant Termination: Upon successful write-back to your environment, the active session and its associated memory buffers are instantly purged - the data is gone from our end the millisecond the job finishes.
Auditability: We retain only minimal, anonymized process telemetry (e.g., row counts, processing logic skips, and billing metadata) in a secured archive for dispute resolution and compliance auditing for SOC 2 and ISO, as required by law.
Model Integrity: We strictly warrant that customer data is never used to train, fine-tune, or improve our AI agents or any global models.
We provide the fix without the footprint—ensuring your data remains your property, and your security posture remains intact.
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Ideal For:
Payment:
Inclusive:
Overage:
Unlike traditional data quality tools which heavily rely on manual rules and SQL queries. Our engine bypasses SQL logic entirely, adopts powerful vertical scaling and compute-demanding Python-based ML to structurally auto-remediate your data records in a RAM-heavy environment which is often more challenging than horizontal scaling. This approach keeps our platform simpler, faster and securer for your workloads.
Pricing is determined by remediation volume, not file size. We measure the total number of cells processed to ensure you only pay for the active remediation of your data assets, ensuring consistent performance across high-density datasets.
The fixed tier pricing and on-demand overage/topup are all you pay, no extra hidden fees. Every job provides a detailed remediation summary, breaking down the total record-field count processed. This ensures total transparency: while formats like Parquet reduce your storage footprint, our pricing remains strictly aligned with the actual logical volume of data points remediated, ensuring you pay for results, not file compression.